Columnar engines like ClickHouse, Snowflake, BigQuery, and Redshift make denormalization cheap and joins fast, which reshapes the classic star-vs-snowflake-schema trade-off. Here is how to choose in 2026.
Almost every "star schema vs snowflake schema" article you will find repeats the same textbook trade-off: star schemas are faster to query, snowflake schemas save storage, pick your poison. That framing dates to the era of row-oriented databases on spinning disks, where every extra join meant another random read and storage was scarce. It is not wrong. On a modern columnar engine, though, most of its assumptions no longer hold.
If you are running analytics on ClickHouse, Snowflake (the warehouse), BigQuery, or Redshift, the math has shifted. Compression makes the "wasteful" duplication of a denormalized star schema close to free, and join algorithms have improved to the point where the join penalty that justified heavy normalization is much smaller than it used to be. This post walks through where the old advice still applies, where columnar storage rewrites it, and how to decide in 2026.
One disambiguation up front, because it trips people up constantly. The snowflake schema is a data modeling pattern. Snowflake is also a cloud data warehouse product. They are unrelated. Where this post means the product it says so; everywhere else, "snowflake schema" is the modeling pattern.
Star and Snowflake Schemas, Defined
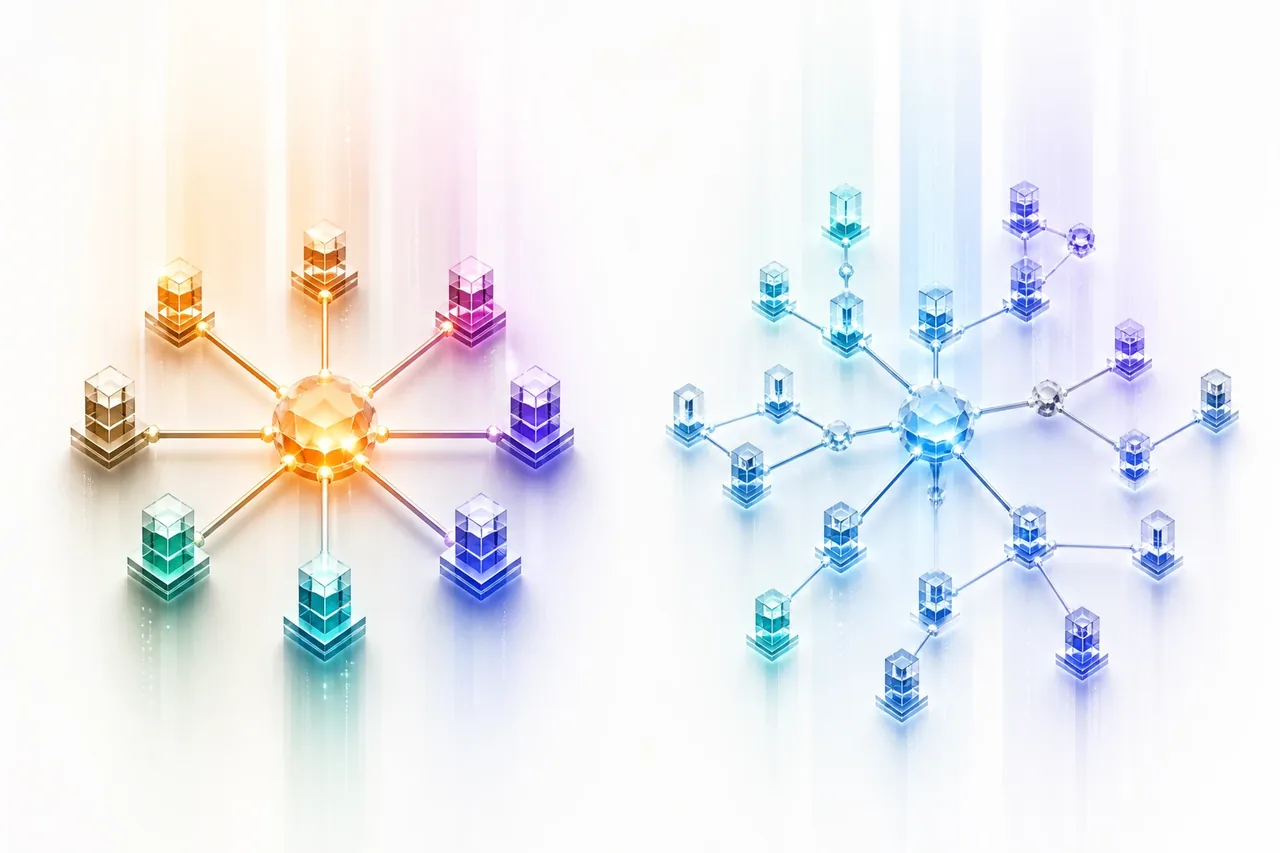
A star schema has one central fact table holding measurements (sales amounts, event counts, durations) joined directly to a set of denormalized dimension tables (customer, product, date), each a single flat table. Queries join the fact table to one or two dimensions, which is why the layout is fast and simple to reason about.
A snowflake schema is a star schema whose dimension tables have been normalized into multiple related sub-tables. A product dimension might split into product, category, and supplier tables linked by foreign keys. This removes redundancy in large hierarchies at the cost of more joins per query and a model that is harder for analysts to navigate.
Both come from Ralph Kimball's dimensional modeling approach, laid out in The Data Warehouse Toolkit (1996) and still the dominant way to structure analytical data (Kimball Group, dimensional modeling techniques). Kimball's own guidance was to avoid snowflaking unless there is a concrete reason for it, such as an unusually large dimension, because the extra joins hurt query performance and confuse users (Star schema, Wikipedia).
A short DDL sketch makes the difference concrete. A star schema keeps the product attributes inline:
CREATE TABLE dim_product (
      product_id   UInt32,
      product_name String,
      category     String,   -- denormalized: repeated for every product in a category
      supplier     String    -- denormalized
  ) ENGINE = MergeTree ORDER BY product_id;
The snowflake version splits the hierarchy out:
CREATE TABLE dim_product  (product_id UInt32, product_name String, category_id UInt16)
      ENGINE = MergeTree ORDER BY product_id;
  CREATE TABLE dim_category (category_id UInt16, category String, supplier_id UInt16)
      ENGINE = MergeTree ORDER BY category_id;
  CREATE TABLE dim_supplier (supplier_id UInt16, supplier String)
      ENGINE = MergeTree ORDER BY supplier_id;
A query against the star schema joins the fact table to one dimension. The same query against the snowflake schema chains three joins to reach the supplier name.
The Textbook Argument (and Where It Stops)
The classic comparison lines up like this, and every top search result stops here.
| Dimension | Star schema | Snowflake schema |
|---|---|---|
| Normalization | Denormalized dimensions | Normalized into sub-dimension tables |
| Storage | More redundancy, larger dimension tables | Less redundancy, smaller dimension tables |
| Joins per query | Few (1-2 per dimension) | Many (chained through the hierarchy) |
| Query/join cost | Lower, fewer joins | Higher, more joins |
| Maintenance & integrity | Updates touch repeated values | Single source of truth per attribute |
| Analyst usability | Simple, intuitive | Harder to navigate |
| Classic verdict | Use for speed | Use to save storage |
The problem is that the two columns people care about most, storage and query cost, were both measured on assumptions that columnar engines break. The storage savings from snowflaking are usually tiny to begin with, because dimension tables are small relative to the fact table. Wikipedia's own worked example (1M sales across 300 shops in 220 countries) finds the record-count difference between the two layouts is about 0.02%, i.e. noise (Snowflake schema, Wikipedia). You are normalizing the smallest tables in the warehouse to save space, while paying a join tax on every query.
How Columnar Storage Changes the Math
Two properties of modern analytical engines undermine the textbook trade-off.
Compression and column pruning make denormalization cheap. Column stores group values of the same type and similar content together, so repeated values (the "redundant" category name copied across every product row) compress extremely well under codecs like LZ4 and ZSTD. ClickHouse reports that 10x to 20x compression on a fact table is typical, with dimension tables compressing even more aggressively because their values are small and repetitive (ClickHouse). The duplication you were trying to avoid largely disappears after compression. Wide tables are also not the liability they are on a row store: columnar engines read only the columns a query touches and process them in vectorized batches, so reading 5 columns out of 80 costs roughly what reading 5 columns out of 5 would. Flattening dimensions into the fact table (or into wide dimension tables) does not penalize unrelated queries.
Joins are far faster than they were. This is the big one. ClickHouse ships multiple join algorithms (parallel hash, grace hash, full sorting merge) and a planner that picks among them by table size and memory. Late-2025 releases added global join reordering in 25.9 and runtime bloom filters in 25.10; on TPC-H the bloom filters alone delivered a 2.1x speedup with a 7x memory reduction, and join reordering with column statistics enabled turned one six-table query from 3,903 seconds into 2.7 seconds (ClickHouse). In a head-to-head star schema benchmark of 17 mostly-join queries across 721 million to 7.2 billion rows, ClickHouse Cloud was faster and cheaper than Snowflake and Databricks at every scale, with no query or engine tuning; at the 1-billion-row scale one query joined, aggregated and sorted 1.7 billion rows in half a second while competitors took 5 to 13 seconds (ClickHouse).
Joins are not free. But the gap between a star schema's few joins and a snowflake schema's many is now small, and a fully denormalized wide table is often cheaper and simpler than either. For more on laying out tables for these engines, see our guide to ClickHouse schema optimization.
When Each Schema Still Wins
Star schema (or a denormalized wide table) wins when:
- You need sub-second BI dashboards. Fewer joins means lower latency and more predictable query plans, which matters when a dashboard fires dozens of concurrent queries.
- A semantic layer or BI tool sits on top. Star schemas map cleanly to tools like Power BI, whose modeling guidance is written around the star pattern and recommends collapsing snowflaked dimensions into single tables (Microsoft Learn).
- Dimensions are small. Normalizing a 10,000-row product dimension to save space is pure overhead on a columnar engine.
Snowflake schema (or fuller normalization) earns its keep when:
- A dimension is huge or has high-cardinality, deeply shared hierarchies, so the redundancy is real. Think of a 200-million-row customer dimension with SCD Type 2 history, where every address change would otherwise re-copy the full geography hierarchy.
- Governance and integrity demand a single source of truth per attribute. Renaming a product category in one 500-row table beats rewriting it across millions of denormalized rows and hoping every copy got updated.
- A sub-dimension is reused across many fact tables. A shared calendar or geography hierarchy referenced by sales, returns, and inventory facts is better as one authoritative table than three drifting copies.
A practical middle ground is the hybrid: keep the frequently queried, small dimensions denormalized for speed, and normalize only the sparse or oversized hierarchies. The galaxy (or fact constellation) schema, where multiple fact tables share conformed dimensions, is the natural extension when you have several business processes to model.
Engine-Specific Notes for 2026
- ClickHouse rewards keeping joins shallow. Its planner is strong, but the cleanest results come from star schemas or wide tables; dictionaries are a good fit for small lookup dimensions, sidestepping joins entirely. The 25.9 and 25.10 join improvements narrow the cost of the joins you do keep. Our ClickHouse vs Snowflake comparison digs into where each engine fits.
- Snowflake (the warehouse) handles both patterns well. In our experience, clustering keys on the fact table matter more for performance than the choice between star and snowflake modeling. See what Snowflake is for the product overview.
- BigQuery offers nested and repeated fields, which let you collapse one-to-many dimensions into a single table and avoid joins in a way neither star nor snowflake assumes.
- Redshift still benefits from classic star-schema discipline. AWS's own table design guidance is to distribute the fact table and its most-joined dimension on their common key, and to replicate small dimensions to every node with
ALLdistribution (AWS docs), which assumes a fact-to-dimension layout.
Across all of them, the decision is less "star or snowflake" and more "how flat can I make this before integrity or maintenance costs outweigh the query savings." Default to a star schema or a wide table on a columnar engine, and reach for snowflaking only for the large, shared, or governance-heavy dimensions listed above. If you are still choosing the engine itself, our guide on how to choose a database for your next project is a good starting point.