Meet us at AWS re:Invent Meet us at AWS re:Invent See our events

Your data, ready for AI. Your AI, ready for production.

Big data consulting, search and AI engineering. Built for production, supported 24/7.

We build and operate the data platforms your AI depends on, ship the agents on top, and stay on call once they're live. For engineering teams who need to run search, analytics and AI at scale.

Trusted in production by engineering teams at

Deep on the engines that matter

Vendor-independent. We recommend what fits your workload, then make it fast.

Data platforms that hold up in production.

Big data consulting services for search, streaming and analytics at scale, by engineers who run these engines in production every day. We work in your cloud and your repo, and you own what we build.

  • Build a new platform

    Architecture, data model and build for search, streaming or analytics, in your cloud.

    Fixed scope

  • Audit what you run

    Architecture, performance, cost and risk, with a prioritized fix list.

    Health assessment

  • Migrate or tune an engine

    Elasticsearch, OpenSearch, Solr, ClickHouse, Kafka, Flink, Spark, Databricks: tuning, upgrades, migrations.

    Fixed scope or retainer

  • 24/7 production support

    Senior engineers on call for Elasticsearch, OpenSearch and ClickHouse, with a guaranteed response time.

    Annual SLA

AI Launchpad

Your AI use case, in production in weeks.

Launched for Max Security, ScreenSteps, Boomi and Bank Hapoalim.
Embed an engineer

A senior data or AI engineer in your team, your repo and your on-call, for a quarter or more.

Meet an engineer →

Not sure which one you need?

Book a free 30-minute call with a senior engineer. If you'd rather start with a full audit, we run a Health Assessment on what you have.

Health Assessment →

Your agents are only as good as their retrieval.

The model is rarely the problem. Stale indexes, slow queries, missing permissions and pipelines nobody owns are. Gartner predicts that through 2026, organizations will abandon 60% of AI projects that lack AI-ready data. That's the layer we've spent a decade on.

  • Retrieval that answers correctly

    Hybrid and semantic search tuned on your real queries, with relevance you can measure.

  • Data that's fresh and governed

    Streaming pipelines and permission-aware indexes, so agents see what users are allowed to see, as it changes.

  • Latency and cost under load

    Capacity planning and tuning from people who have run multi-terabyte clusters for years.

  • Someone on call after launch

    Evals, observability and 24/7 support, so it keeps working after the demo.

Shipped, and still running

All customer stories →

AI in production

Data platforms at scale

The OpenSearch Experts.

15+ years in Elasticsearch and OpenSearch. We contribute to the OpenSearch project, maintain open-source plugins for it, and ship BDB OpenSearch Enterprise.

  • Accredited LTS support provider

    The first accredited provider in the OpenSearch Software Foundation's Long-Term Support program.

    Read the announcement →
  • OpenSearch Software Foundation member

    Members of the vendor-neutral home for the OpenSearch project, under the Linux Foundation.

    Our partners →
  • An OpenSearch Ambassador on the team

    Our team includes an official OpenSearch Ambassador, and we have contributed to the project since its earliest days.

  • Amazon OpenSearch Service Delivery

    An AWS-validated designation for teams running the managed service.

    Our AWS partnership →
AWS Partner — Advanced Tier Services AWS Partner — Amazon OpenSearch Service Delivery AWS Partner — AI Services Competency

Your AWS Data & Analytics Partner

We're an AWS Advanced Tier Services Partner with the Amazon OpenSearch Service Delivery designation and the AWS AI Services Competency. AWS has vetted our team's technical skills and customer track record.

We design, deploy and operate data stacks on AWS, from Amazon OpenSearch Service and Amazon MSK to Amazon EMR and AWS Glue. The partnership also opens up AWS-funded proof-of-concept programs, migration incentives and direct work with AWS solution architects.

Our AWS partnership →
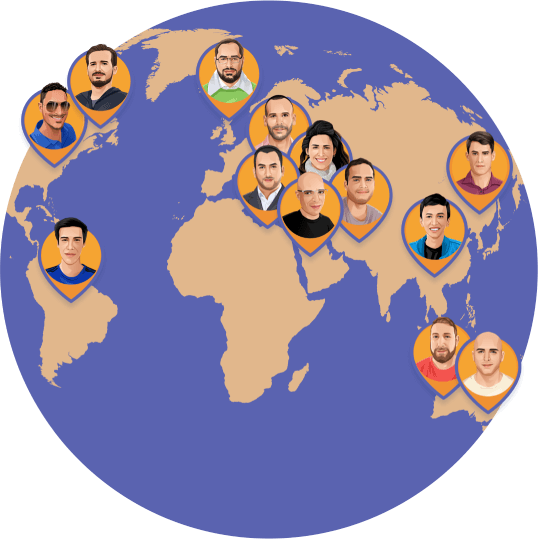
BigData Boutique engineers across the world

A small team of experts, working globally

BigData Boutique is small by design. Our big data consultants work across several continents with customers in the United States, Europe, Israel and beyond, and every one of them is a senior specialist in the engines we support.

We hand-pick and train every engineer in-house, and they work hands-on in production systems every day. You get people who have seen your problem before, not a bench of generalists.

The engineers who scope your project are the ones who build and support it, from enterprise search and logging to streaming, analytics and AI in production.

Big data consulting services

What our big data consultants do, by practice. Every engagement is run by senior engineers and can be backed by 24/7 support.

  • Data engineering services

    Pipelines, real-time streaming and lakehouse design on Kafka, Flink, Spark, Iceberg and ClickHouse.

    Data engineering consulting

  • Data platform consulting

    Architecture, technology selection, cost and migrations for data platforms on AWS and other clouds.

    Architecture and modernization

  • AI consulting services

    RAG, agents, evals and guardrails, from use-case fit to a system that runs in production.

    AI and generative AI

  • Machine learning consulting

    Use-case discovery, model development, ML pipelines and MLOps.

    ML and MLOps

By engine: Elasticsearch consulting, OpenSearch consulting, ClickHouse consulting, Apache Kafka consulting, Apache Flink consulting, Apache Spark consulting, Databricks consulting and Elasticsearch support. All services →

Big Data Consulting FAQ

What is big data consulting?

Big data consulting helps organizations design, build, operate, and optimize platforms that handle high volume, high velocity, or highly varied data. It typically spans architecture, technology selection, implementation, migrations, performance tuning, cost optimization, and ongoing production support across systems like Elasticsearch, OpenSearch, Apache Flink, Apache Kafka, ClickHouse, Databricks, and Apache Spark.

What does a big data consultant do?

A big data consultant designs, builds and fixes the systems that store, move and query large volumes of data. Day to day that means choosing the right engines, designing schemas and pipelines, planning capacity, tuning slow queries, running migrations and upgrades, cutting infrastructure cost, and helping the in-house team operate the platform. Our big data consultants are senior engineers who do this work hands-on in production, not advisors who hand over a slide deck.

What big data consulting services does BigData Boutique offer?

Our big data consulting services cover data engineering services for pipelines, streaming and lakehouse platforms, data platform consulting for architecture, cost and migrations, search engineering on Elasticsearch and OpenSearch, AI consulting services for RAG and agents, and 24/7 production support. Engagements run as fixed-scope projects, retainers, annual support subscriptions or embedded engineers.

What does BigData Boutique do?

BigData Boutique is a specialist big data consultancy and AI engineering company. We design and operate production-grade data platforms on Elasticsearch, OpenSearch, Apache Flink, Apache Kafka, ClickHouse, Databricks, Spark and modern lakehouse architectures, and build the RAG, semantic search and agentic systems that run on them. Our work covers consulting, implementation, migrations, 24/7 enterprise support, and cost and performance optimization for Fortune 100 enterprises and high-growth startups, with consultants across multiple continents serving customers in the United States, Europe, Israel and beyond.

Which technologies does BigData Boutique specialize in?

Our core specializations include Elasticsearch, OpenSearch, Apache Flink, Apache Kafka, Apache Spark, ClickHouse, Databricks, Apache Iceberg, AWS data and analytics services (Amazon OpenSearch Service, MSK, EMR, Glue, Athena), vector search and semantic search, and retrieval-augmented generation (RAG) and agentic AI workloads.

How is BigData Boutique different from other big data consulting companies?

Most big data consulting firms are generalists. We are a specialist boutique. Every consultant is a senior practitioner, hand-picked and trained in-house, working with customers across multiple continents. We are an AWS Advanced Tier Services Partner with Amazon OpenSearch Service Delivery designation and AWS AI Services Competency, members of the OpenSearch Software Foundation under the Linux Foundation, and an accredited OpenSearch LTS support provider. We commit to specific platforms in depth rather than offering a generic consulting catalog.

Which companies offer OpenSearch support?

The OpenSearch Software Foundation accredits commercial support providers through its Long-Term Support program. BigData Boutique was the first accredited provider in that program and offers 24/7 OpenSearch support for both self-managed OpenSearch and Amazon OpenSearch Service, with an official OpenSearch Ambassador on the team. Amazon OpenSearch Service customers can also use AWS Support for the managed service itself.

Do you provide 24/7 production support?

Yes. We offer enterprise-grade 24/7 production support for Elasticsearch, OpenSearch, ClickHouse, Apache Flink, and the broader big data stack, including SLAs, on-call coverage, and proactive monitoring through our Pulse platform.

Can you help reduce our Elasticsearch or OpenSearch cost?

Yes. Cost and performance optimization is one of our most common engagements. We routinely cut Elasticsearch and OpenSearch infrastructure spend through index design, sharding strategy, hardware right-sizing, hot/warm/cold tiering, query optimization, and migration between Elastic Cloud, Amazon OpenSearch Service, and self-managed deployments.

How long does it take to get an AI use case into production?

Through AI Launchpad, the path is about eight weeks: use-case fit in week 1, building on your real data in weeks 2 to 5, and hardening for production in weeks 6 to 8, followed by launch and ongoing support. Your data, integrations and security review set the exact scope.

Can you embed an engineer in our team?

Yes. A named senior data or AI engineer can work part-time or full-time inside your team, your repositories and your on-call for a quarter or longer, backed by our specialists. You interview the engineer first. Some teams call this role a forward deployed engineer.

Bring a use case or a struggling cluster.

In one call with a senior engineer you'll know what it takes to get it into production, or back to healthy.

or Contact Us

Leave your contact details below and our team will be in touch within one business day or less.

By clicking the “Get Expert Help” button below you’re agreeing to our Privacy Policy
We use cookies to provide an optimized user experience and understand our traffic. To learn more, read our use of cookies; otherwise, please choose 'Accept Cookies' to continue using our website.